Using OAuth with Project Antalya
Altinity’s Project Antalya supports authenticating users via OAuth tokens issued by an external Identity Provider (IdP) such as Keycloak, Microsoft Entra ID, the Google Auth Platform or any service that supports OpenID Connect (OIDC). This allows you to manage users at an organizational level instead of defining them in ClickHouse and other systems.
OAuth support first shipped in Altinity Antalya 26.1, and is officially GA as of Altinity Antalya 26.3.
The power of OAuth
When someone or something authenticates with an IdP, they get three tokens:
- An access token that tells ClickHouse the roles held by anyone who has this token. The token also has an expiration timestamp that indicates when it is no longer valid.
- A refresh token that ClickHouse can use to get a new access token from the IdP when it expires.
- An ID token that identifies a user or application.
A ClickHouse server configured to use OAuth manages these tokens for you. A refresh token typically has a much longer lifecycle than an access token. If the access token has expired, ClickHouse can send the refresh token to the IdP to get a new one. If the refresh token has expired as well, the user or application has to reauthenticate with the IdP.
Most importantly, given the claims in an access token, ClickHouse can determine what roles and grants the holder of that access token should have. This is especially useful for managing access permissions for an LLM. With OAuth in the picture, the LLM sends an access token to ClickHouse with a query; the access token tells ClickHouse exactly what access the LLM has. An LLM can’t work around access limits by asking a question a different way with a different query — if the LLM’s access token doesn’t give it the access it needs to run a query, the query will fail. You have the simplicity of managing users with OAuth without giving up the full power of ClickHouse’s RBAC.
Managing access to ClickHouse with OAuth has substantial advantages over a static username and password:
- Tokens expire - Even if a credential is compromised, its lifespan is short, so the potential for damage is limited.
- Fine-grained access control - Given the claims in an access token, ClickHouse can determine exactly what roles and grants apply.
- Audit trail - An OAuth server provides a full audit trail of every token issued to a service account.
Antalya uses OpenID Connect (OIDC). OIDC adds claims to OAuth tokens, adding information about the token holder’s identity. (Claims are often called fields, but “claim” is the official OIDC term. For example, the name/value pair 'email': 'doug@example.com' is a claim.) We’ll configure Antalya to control access based on the values of those claims.
To use OAuth, we’ll need to do three tasks:
- Enable token authentication - It’s a global setting enabled by default. Pretty straightforward.
- Define token processors - We can define any number of token processors to work with the IdPs that manage the tokens we’ll use. We can set these up in several different configurations; we’ll talk about the pros and cons of each.
- Set up an IdP as an external user directory - A major advantage of OAuth is that we can manage access for users that aren’t defined to ClickHouse. If a token belongs to a user ClickHouse doesn’t know, we can go to an external user directory to determine what access (if any) that user should have.
Enabling token authentication
You don’t need to do anything here; token authentication is enabled by default. However, you can disable it in config.xml if you want:
<enable_token_auth>0</enable_token_auth>
When disabled, token processors are not parsed, TokenAccessStorage is not available, and authentication via tokens (with the clickhouse-client --jwt option or by passing an Authorization: Bearer header) is rejected.
Enabling token authentication for a ClickHouse user
In an OAuth environment, users are typically managed by the IdP. However, you can also create a ClickHouse user that should be authenticated with a token instead of other methods. Enabling token authentication with SQL is simple:
CREATE USER my_user IDENTIFIED WITH jwt;
You can also enable token authentication for a user in users.xml. Use the jwt section instead of password or other similar sections in the user definition:
<clickhouse>
  <my_user>
    <jwt>
      <claims>{"resource_access":{"account": {"roles": ["view-profile"]}}}</claims>
    </jwt>
  </my_user>
</clickhouse>
Here, the claims element says the JSON Web Token (JWT) payload must contain ["view-profile"] on path resource_access.account.roles, otherwise authentication will fail. Per-user claims are enforced only when the token is a JWT (validated by a JWT processor such as jwt_static_key or jwt_dynamic_jwks). When the user authenticates with an opaque (access) token (for example, from Azure, OpenID, or Google token processors), claims are not checked and authentication succeeds if the token is otherwise valid.
NOTE: A user definition cannot have JWT authentication together with any other authentication method. The presence of any other sections such as password alongside jwt will force ClickHouse to shut down.
Enabling token forwarding for data lake catalogs
Token forwarding tells Antalya to forward tokens to data lake catalogs. For example, you can associate an AWS Glue catalog with the same IdP you’re using for ClickHouse, then use token forwarding to pass the token to the catalog with every query. Enabling it is simple:
<enable_token_forwarding>1</enable_token_forwarding>
Defining token processors
There are several ways to define a token processor to Antalya. To use token authentication, you need to add a token_processors section to config.xml and define at least one token processor in it. There are several types of token processor, and we’ll look at the details of all of them, but first we need to talk about the architecture of our application and look at JSON Web Tokens, the most common data format for tokens.
Application architecture
At a high level, there are two ways to set up a token processor:
- Validate tokens locally - The first time a token comes in from a particular IdP, Antalya gets its public key. From that point, Antalya uses the IdP’s public key to verify the signature in every token it receives.
- Pros: No network latency; we don’t have to go to the IdP for every token.
- Cons: If a token hasn’t expired, ClickHouse blindly accepts it. It’s possible that the token holder’s access has been revoked at the IdP. Until the token expires, the token holder will get access they’re not entitled to.
- Validate tokens remotely - ClickHouse calls the IdP’s userinfo endpoint on every token.
- Pros: If the token holder’s access has been revoked at the IdP, the token will be rejected immediately.
- Cons: We’ve got a network call for every single token. That puts the IdP in our critical path.
Which one you choose mainly depends on the sensitivity of your data. If you’re working with financial data or anything with privacy concerns, you’ll need to validate tokens remotely. On the other hand, if you’re okay with a token holder potentially having unauthorized access until a token expires, you can use the local approach. Finally, if your IdP works with opaque tokens (tokens that are a string instead of a JSON object), you’ll have to validate those tokens remotely.
JSON Web Tokens
Most of the tokens we’ll work with are JSON Web Tokens. A JWT has three sections:
- Header: - Contains the ID of an IdP’s public key and the algorithm used to sign the token
- Payload: The data we care about. It includes claims for things like the URL of the IdP who issued the token, a unique ID for the holder of the token, an expiration timestamp, and the groups the token holder belongs to.
- Signature: The token’s signature, created with the IdP’s private key. We can use the IdP’s public key to verify the signature.
Determining the access a token holder should have involves verifying the signature and then looking at the values in the payload.
Be aware there are also opaque tokens, which are strings that don’t use the JWT structure. (7f8d9e4b-1234-5678-9876543210ef, for example.) If that’s what we’re working with, we have to configure the token processor to take every token it receives and send it to the IdP for verification.
There are three ways Antalya can store an IdP’s public key:
- Static public key: We get the public key of the IdP and hardcode it into the definition of the token processor. Verifying the token simply means checking the signature against the hardcoded public key. However, if the IdP rotates its keys, we have to reconfigure the token processor.
- Static JSON Web Key Set (JWKS): A JWKS is a JSON document that contains one or more public keys. Each key has an ID defined by the IdP, and every token signed by the IdP includes the token ID in its header. Verifying a token means getting the key ID in the token’s header, finding the public key with that ID, then checking the signature against the key. We can store the JWKS in a file and reference the filename, or we can put the contents of the JWKS in the configuration itself. As you would expect, if the key set changes, we have to reconfigure the token processor.
- Dynamic JWKS: We configure the token processor by giving it the URL of the JWKS at the IdP. As with a static JWKS, the token processor finds the public key that matches the ID in the token header and validates the signature. However, if the token processor gets a token with a key ID it doesn’t recognize, the token processor goes back to the IdP and downloads an updated key set. We can also configure the token processor to update the key set on an interval. This is the configuration you would use in production with a real IdP.
Basic syntax and parameters
We define one or more token processors in the token_processors section of config.xml. As an example, here’s the partial definition of a token processor named keycloak:
<clickhouse>
  <token_processors>
    <keycloak>
      <type>openid</type>
      <token_cache_lifetime>60</token_cache_lifetime>
      <username_claim>email</username_claim>
      . . .
    </keycloak>
  </token_processors>
</clickhouse>
There are four parameters common to every type of processor:
type- The type of token processor. Supported values arejwt_static_key,jwt_static_jwks,jwt_dynamic_jwks,entra, andopenid. (We’ll look at the details of each of the five types next.) Mandatory, case-insensitive.token_cache_lifetime- The maximum lifetime of a cached token in seconds. If the token reaches its expiration before the cache, it is no longer valid. If the cache lifetime is reached, the token is no longer valid, even if its expiration date hasn’t been reached. Optional, default:3600.username_claim- The name of the claim in the payload of a JWT that will be treated as the ClickHouse username. Optional, default:sub.groups_claim- The name of the claim that contains the list of groups the user belongs to. Optional, default:groups.
There are additional specific parameters for each token processor type, some of which are mandatory. We cover those next. Be aware that any parameters that are not required for a given processor type are ignored.
Static public key token processor
We need to define the signing algorithm and the key:
<clickhouse>
  <token_processors>
    <my_static_key_validator>
      <type>jwt_static_key</type>
      <algo>HS256</algo>
      <static_key>my_static_secret</static_key>
    </my_static_key_validator>
  </token_processors>
</clickhouse>
Parameters:
algo- The algorithm for signature validation. Mandatory. Supported values:
| HMAC | RSA | ECDSA | PSS | EdDSA |
|---|---|---|---|---|
| HS256 | RS256 | ES256 | PS256 | Ed25519 |
| HS384 | RS384 | ES384 | PS384 | Ed448 |
| HS512 | RS512 | ES512 | PS512 | |
| ES256K |
None is also supported, but it is not recommended and must NEVER be used in production.
static_key- The key for symmetric algorithms. Mandatory forHS*family algorithms.public_key- The public key for asymmetric algorithms. Mandatory except forHS*family algorithms andNone.claims- A string containing a JSON object that should be contained in the token payload. If this parameter is defined, a token without a corresponding payload will be considered invalid. Optional.static_key_in_base64- Indicates if thestatic_keykey is base64-encoded. Optional, default:False.private_key- The private key for asymmetric algorithms. Optional.public_key_password- The public key password. Optional.private_key_password- The private key password. Optional.expected_issuer- The expected value of theiss(issuer) claim in the JWT. If specified, tokens with a different issuer will be rejected. Optional.expected_audience- The expected value of theaud(audience) claim in the JWT. If specified, tokens with a different audience will be rejected. Optional.allow_no_expiration- Iftrue, tokens without theexp(expiration) claim are accepted. Otherwise they are rejected. Optional, default:false.
Static JWKS processor
We need to define the JWKS to the processor, either by storing it in a file and using the filename or putting its contents directly into the XML.
<clickhouse>
  <token_processors>
    <my_static_jwks_validator>
      <type>jwt_static_jwks</type>
      <static_jwks>{"keys": [{"kty": "RSA", "alg": "RS256", "kid": "mykid", "n": "_public_key_mod_", "e": "AQAB"}]}</static_jwks>
    </my_static_jwks_validator>
  </token_processors>
</clickhouse>
Parameters:
static_jwks- The content of the JWKS in JSON.static_jwks_file- The path to a file with the JWKS data.
NOTE: You must define eitherstatic_jwksorstatic_jwks_file. If you define both or neither, the configuration will not be parsed and the token processor will not be used.claims- A string containing a JSON object that should be contained in the token payload. If this parameter is defined, a token without the corresponding payload will be considered invalid. Optional.verifier_leeway- Specifies the clock skew tolerance in seconds. Useful for handling small differences in system clocks between ClickHouse and the token issuer. Optional.expected_issuer- The expected value of theiss(issuer) claim in the JWT. If specified, tokens with a different issuer will be rejected. Optional.expected_audience- The expected value of theaud(audience) claim in the JWT. If specified, tokens with a different audience will be rejected. Optional.allow_no_expiration- Iftrue, tokens without theexp(expiration) claim are accepted. Otherwise they are rejected. Optional, default:false.
NOTES:
- For JWKS-based validators (
jwt_static_jwksandjwt_dynamic_jwks), RS* and ES* family algorithms are supported.
Dynamic JWKS processor
<clickhouse>
  <token_processors>
    <my_dynamic_jwks_validator>
      <type>jwt_dynamic_jwks</type>
      <jwks_uri>http://localhost:8000/.well-known/jwks.json</jwks_uri>
      <jwks_cache_lifetime>3600</jwks_cache_lifetime>
    </my_dynamic_jwks_validator>
  </token_processors>
</clickhouse>
Parameters:
jwks_uri- The JWKS endpoint. Mandatory.jwks_cache_lifetime- The time period in seconds between resend requests for refreshing the JWKS. Optional, default:3600.claims- A string containing a JSON object that should be contained in the token payload. If this parameter is defined, a token without a corresponding payload will be considered invalid. Optional.verifier_leeway- Specifies the clock skew tolerance in seconds. Useful for handling small differences in system clocks between ClickHouse and the token issuer. Optional.expected_issuer- The expected value of theiss(issuer) claim in the JWT. If specified, tokens with a different issuer will be rejected. Optional.expected_audience- The expected value of theaud(audience) claim in the JWT. If specified, tokens with a different audience will be rejected. Optional.allow_no_expiration- Iftrue, tokens without theexp(expiration) claim are accepted. Otherwise they are rejected. Optional, default:false.
Microsoft Entra ID
To use Microsoft Entra ID, you need to provide your tenant_id:
<clickhouse>
  <token_processors>
    <entra_prod>
      <type>entra</type>
      <tenant_id>aaaabbbb-0000-cccc-1111-dddd2222eeee</tenant_id>
    </entra_prod>
  </token_processors>
  <user_directories>
    <token>
      <processor>entra_prod</processor>
      <common_roles>
        <token_test_role_1 />
      </common_roles>
    </token>
  </user_directories>
</clickhouse>
Parameters:
tenant_id- Your Microsoft tenant ID (a GUID, or an*.onmicrosoft.comdomain). Mandatory. Multi-tenant aliases (common,organizations,consumers) are rejected becauseJwksJwtProcessordoes exact-match issuer validation.
The remaining parameters are optional:
jwks_uri— Override for the JWKS endpoint. Default:https://login.microsoftonline.com/{tenant_id}/discovery/v2.0/keys. Override only for sovereign clouds (login.microsoftonline.us,login.partner.microsoftonline.cn).expected_issuer— Expected value of theissclaim. Default:https://login.microsoftonline.com/{tenant_id}/v2.0(derived fromtenant_id). Override for v1.0 tokens (https://sts.windows.net/{tenant_id}/) or sovereign clouds.expected_audience— Expected value of theaudclaim, normally your app’s Application ID URI (e.g.api://clickhouse) or client ID. If not set, no audience check is performed, so any token will authenticate if its signature is valid. A warning is logged at startup so the gap is visible.username_claim— JWT claim to use as the ClickHouse username. Default:sub. Common Entra alternatives:preferred_username,upn,oid.groups_claim— JWT claim that carries the array of group identifiers. Default:groups. Set toroleswhen using App Roles. See Mapping groups to ClickHouse roles below for details of how to get human-readable values instead of GUIDs.verifier_leeway- Specifies the clock skew tolerance in seconds. Useful for handling small differences in system clocks between ClickHouse and the token issuer. Optional.jwks_cache_lifetime- The time period in seconds between resend requests for refreshing the JWKS. Optional, default:3600.claims- A string containing a JSON object that should be contained in the token payload. If this parameter is defined, a token without a corresponding payload will be considered invalid. Optional.allow_no_expiration- Iftrue, tokens without theexp(expiration) claim are accepted. Otherwise they are rejected. Optional, default:false.token_cache_lifetime- The maximum lifetime of a cached token in seconds. Optional, default:3600.
Mapping groups to ClickHouse roles
By default the groups claim contains group object IDs (GUIDs), not names. There are three ways to surface human-readable identifiers, in order of preference:
Option A — App Roles (recommended)
Operator-chosen role strings in a separate roles claim. Compact even for users in many groups (no hasgroups overage indicator), and immune to Entra-side group renames.
- App registration → App roles → Create app role. Set
Valueto the string ClickHouse should receive (e.g.ch_admin);Allowed member types=Users/Groups. - Enterprise application → Properties →
Assignment required= Yes. - Enterprise application → Users and groups → assign each user or security group to a role. Group assignment requires Entra ID P1/P2; free-tier tenants can only assign individual users here.
- On the processor:
<groups_claim>roles</groups_claim>.
Option B — Format the groups claim
Names emitted in the existing groups claim. Works on free tier; useful when group membership is already maintained in Entra and a separate role-assignment surface is not wanted.
Prerequisites in the app registration:
"groupMembershipClaims": "ApplicationGroup"(or"SecurityGroup"for tenant-wide).optionalClaims.accessTokenentry forgroupswithadditionalPropertiesset to one or more of:
| Value | Effect |
|---|---|
sam_account_name |
On-prem-synced groups emit as sAMAccountName. |
dns_domain_and_sam_account_name |
On-prem-synced groups emit as DOMAIN\sAMAccountName. |
cloud_displayname |
Cloud-only groups emit their displayName. |
Entra picks per group; groups not covered by a chosen format still emit as GUIDs. Display names are mutable — a rename in Entra silently breaks the mapping until config is updated.
Leave <groups_claim>groups</groups_claim> (the default).
Option C — roles_mapping
Keep GUIDs in the token and translate them in the user-directory config (see Using an IdP as an external user directory below). Always works, including on free tier. Tedious for many groups but immune to renames.
NOTE: When switching from GUIDs to names, retune any roles_filter regex — for example \bclickhouse-[a-zA-Z0-9]+\b will not match strings like ch_admin.
Generic OpenID processors
OpenID token processors are flexible, generic processors to handle a wide variety of IdPs. They can be configured to validate tokens locally or remotely:
<clickhouse>
  <token_processors>
    <keycloak>
      <type>openid</type>
      <userinfo_endpoint>http://keycloak:8080/realms/grafana/protocol/openid-connect/userinfo</userinfo_endpoint>
      <token_introspection_endpoint>http://keycloak:8080/realms/grafana/protocol/openid-connect/token/introspect</token_introspection_endpoint>
      <introspection_client_id>clickhouse-rs</introspection_client_id>
      <introspection_client_secret>...</introspection_client_secret>
      <token_cache_lifetime>60</token_cache_lifetime>
    </keycloak>
  </token_processors>
</clickhouse>
Parameters:
- To validate every token locally:
configuration_endpoint- The URI of the OpenID configuration (often ends with.well-known/openid-configuration).
- To validate every token remotely (required for opaque tokens):
userinfo_endpoint- The URI of the endpoint that returns user information in exchange for a valid token.token_introspection_endpoint- The URI of the token introspection endpoint (returns information about a valid token).
NOTE: As shown above, if you have atoken_introspection_endpoint, you must also have anintrospection_client_idandintrospection_client_secret.jwks_uri- The URI of the OpenID configuration (often ends with.well-known/jwks.json). Optional.
NOTE: Eitherconfiguration_endpointor bothuserinfo_endpointandtoken_introspection_endpoint(and, optionally,jwks_uri) must be set. If none of them are set or all three are set, this is an invalid configuration that will not be parsed and the token processor will not be used.
jwks_cache_lifetime- The time period in seconds between resend requests for refreshing the JWKS. Optional, default:3600.verifier_leeway- Specifies the clock skew tolerance in seconds. Useful for handling small differences in system clocks between ClickHouse and the token issuer. Optional, default:60expected_issuer- The expected value of theiss(issuer) claim in the JWT. If specified, tokens with a different issuer will be rejected. Optional.expected_audience- The expected value of theaud(audience) claim in the JWT. If specified, tokens with a different audience will be rejected. Optional.allow_no_expiration- Iftrue, tokens without theexp(expiration) claim are accepted. Otherwise they are rejected. Optional, default:false.
Sometimes a token is a valid JWT. In that case, the token will be decoded and validated locally if the configuration endpoint returns a JWKS URI (or jwks_uri is specified alongside userinfo_endpoint and token_introspection_endpoint).
Using an IdP as an external user directory
If the username in a token is not pre-defined in ClickHouse, authentication is still possible: The IdP can be used as source of user information. To allow this, add a token section to the user_directories section of the config.xml file.
At each login attempt, ClickHouse tries to find the user definition locally and authenticate it as usual. If a token is provided but the user is not defined, ClickHouse will treat the user as externally defined and will try to validate the token and get user information from the specified processor. If validated successfully, the user will be considered existing and authenticated. The user will be assigned roles from the list specified in the roles section. All this implies that the SQL-driven Access Control and Account Management is enabled and roles are created using the CREATE ROLE statement.
Example
<clickhouse>
  <user_directories>
    <token>
      <processor>token_processor_name</processor>
      <common_roles>
        <token_test_role_1 />
      </common_roles>
      <default_profile>my_profile</default_profile>
      <roles_filter>
        \bclickhouse-[a-zA-Z0-9]+\b
      </roles_filter>
      <roles_transform>s/-/_/g</roles_transform>
    </token>
  </user_directories>
</clickhouse>
NOTE: For now, no more than one token section can be defined inside user_directories. This may change in the future.
Parameters
processor— The name of one of the processors defined in atoken_processorsconfig section as described above (my_static_key_validator,my_static_jwks_validator,my_dynamic_jwks_validator,entra_prod, orkeycloak). This parameter is mandatory.common_roles— A list of locally defined roles that will be assigned to each user retrieved from the IdP. Optional.default_profile— The name of a locally defined settings profile that will be assigned to each user retrieved from the IdP. If the profile does not exist, a warning will be logged and the user will be created without a profile. Optional.roles_filter— A regex string for groups filtering. Only groups matching this regex will be mapped to roles. Optional.roles_transform— A sed-style substitution pattern to apply to group names before mapping to roles. Format:s/pattern/replacement/flags. Thegflag applies the replacement globally (all occurrences). In the example above,s/-/_/gconvertsclickhouse-grp-dbatoclickhouse_grp_dba. (Keycloak group names can use hyphens, while names in the SQL world tend to use underscores; the substitution pattern fixes that for us.) Optional.
Using token forwarding with data lake catalogs
Beginning with Antalya version 26.6.8.20003, databases defined with the DataLakeCatalog engine that have a catalog_type of rest or glue can use authentication tokens. As an example, we’ll look at an AWS Glue catalog that is accessed through the same IdP that we’re using for ClickHouse.
We’ll start by creating a catalog, then we’ll set up the IAM infrastructure, then we’ll create the database that uses token forwarding.
Creating and loading the catalog
Here’s what we’ll do:
- Create an S3 bucket with the AWS Glue folder structure (
raw/,warehouse/, andathena-results/) - Create an AWS Glue database (an empty place to hold our data)
- Load some Parquet files into the S3 bucket’s
raw/folder - Create and run a crawler to process the Parquet files and create a Hive-style table, inferring the schema from the Parquet data
- Create an Iceberg table from the first table, creating new Parquet files and Iceberg metadata in the process
That’s a little involved, but it’s what we need to do to get the raw Parquet files into a format ClickHouse can use as a data lake catalog.
Creating the S3 bucket and its folders
This part is straightforward; create a bucket and the three folders mentioned above. For flexibility, we created a bucket named gluetest and put that structure inside a folder named oauth-test:
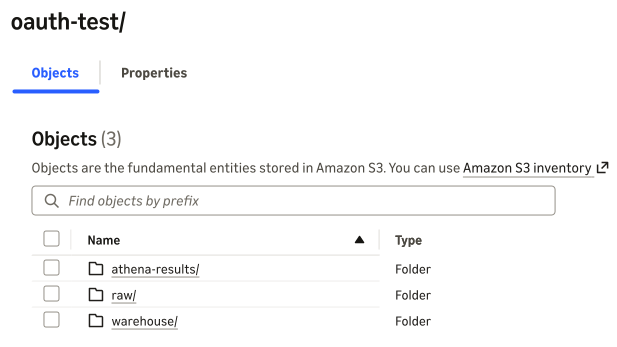
Figure 1 - The S3 bucket layout for our AWS Glue database
This folder structure lets us create another AWS Glue database as a peer of the oauth-test folder.
Creating a Glue database
From the AWS Glue console, click Databases in the left panel, then click the  button in the upper right corner. In the Create a database dialog, create a new database called
nyc_taxi and point it at the warehouse/ folder:
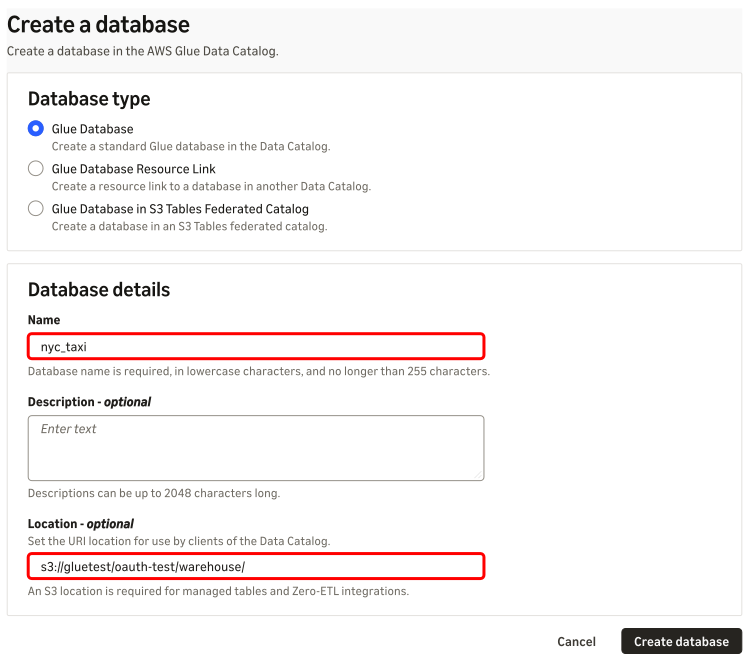
Figure 2 - Creating a new Glue database
In the following steps, we’ll create a couple of tables inside the nyc_taxi database.
Loading Parquet data into the S3 bucket
We’ll use some Parquet files from the NYC Taxi rides dataset. We loaded the files for the first nine months of 2025 into a folder named raw/yellow/. The folder looks like this:
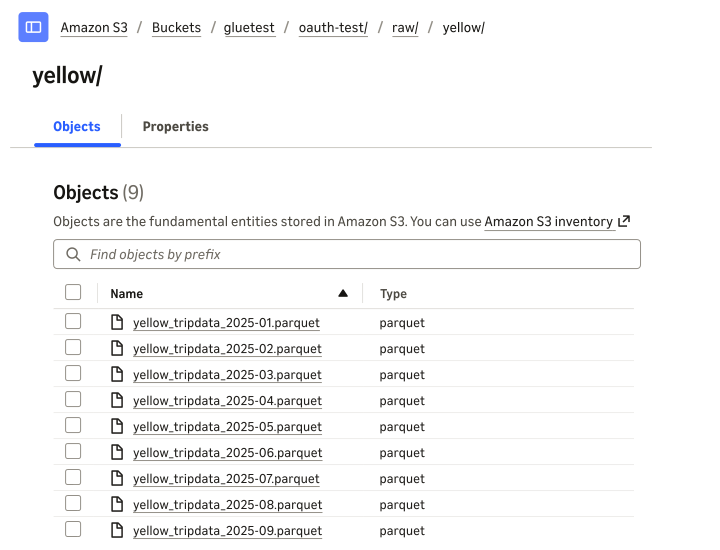
Figure 3 - The raw data in our bucket
Creating and running a crawler to process the Parquet files
We’ll create a crawler to read the schema of our Parquet files and create a Hive-style table. In the AWS Glue console, click Crawlers in the left panel, then click the  button in the upper right corner.
Name the crawler nyc_taxi_crawler and click Next:
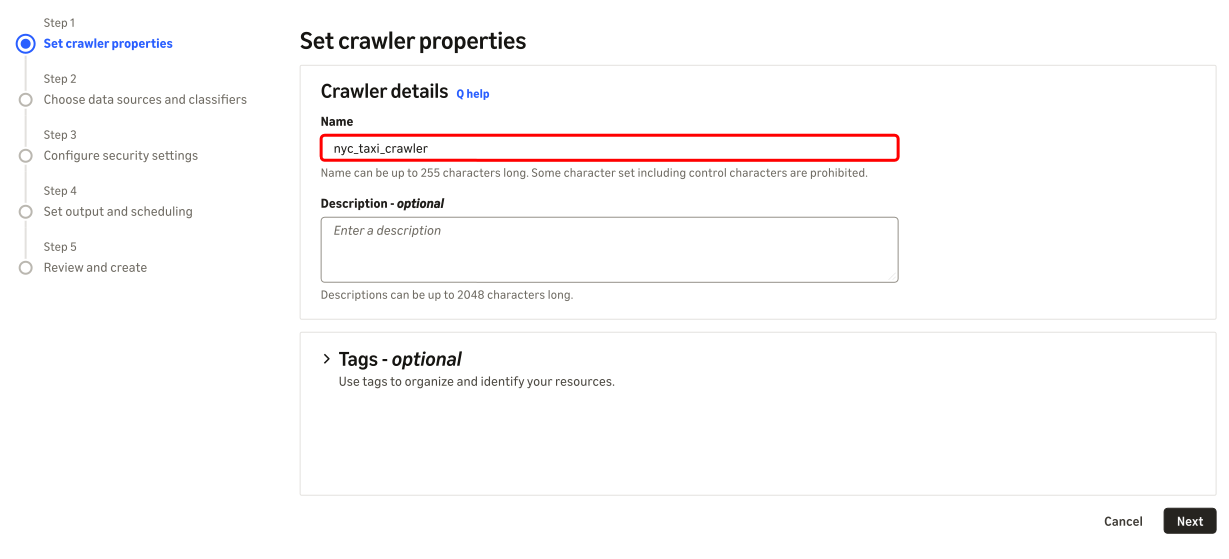
Figure 4 - Naming the crawler
For step 2, click the  button on the right side of the dialog and create a new data source. The data source is the folder where we loaded our Parquet files:
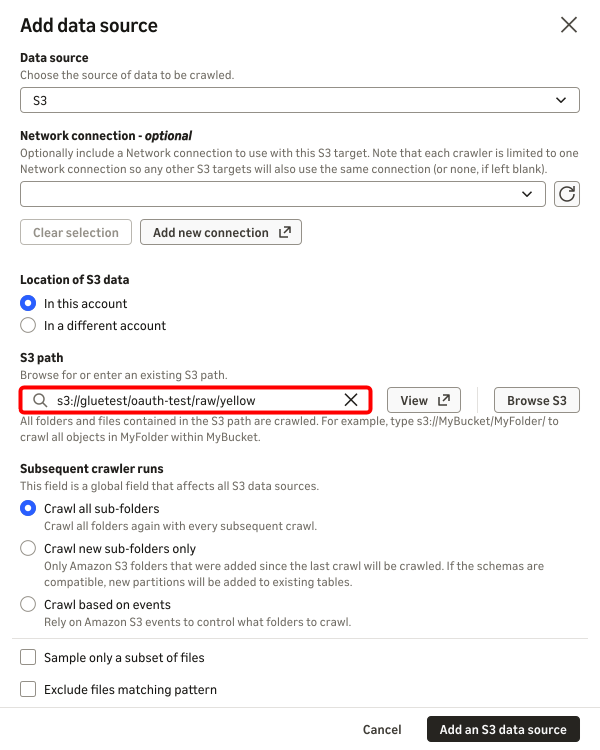
Figure 5 - Adding a data source from an S3 folder
Make sure the new data source is selected, then click Next:
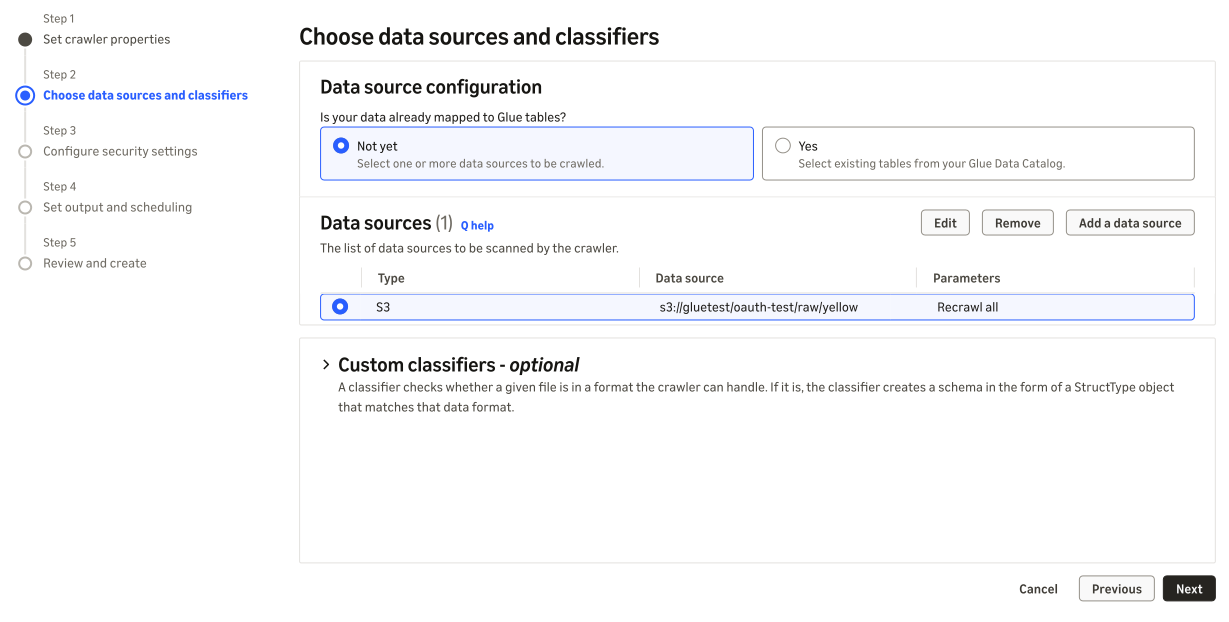
Figure 6 - Choosing a data source
Have the wizard create a default role for you. Add oauth-test to the role name, then click Next:
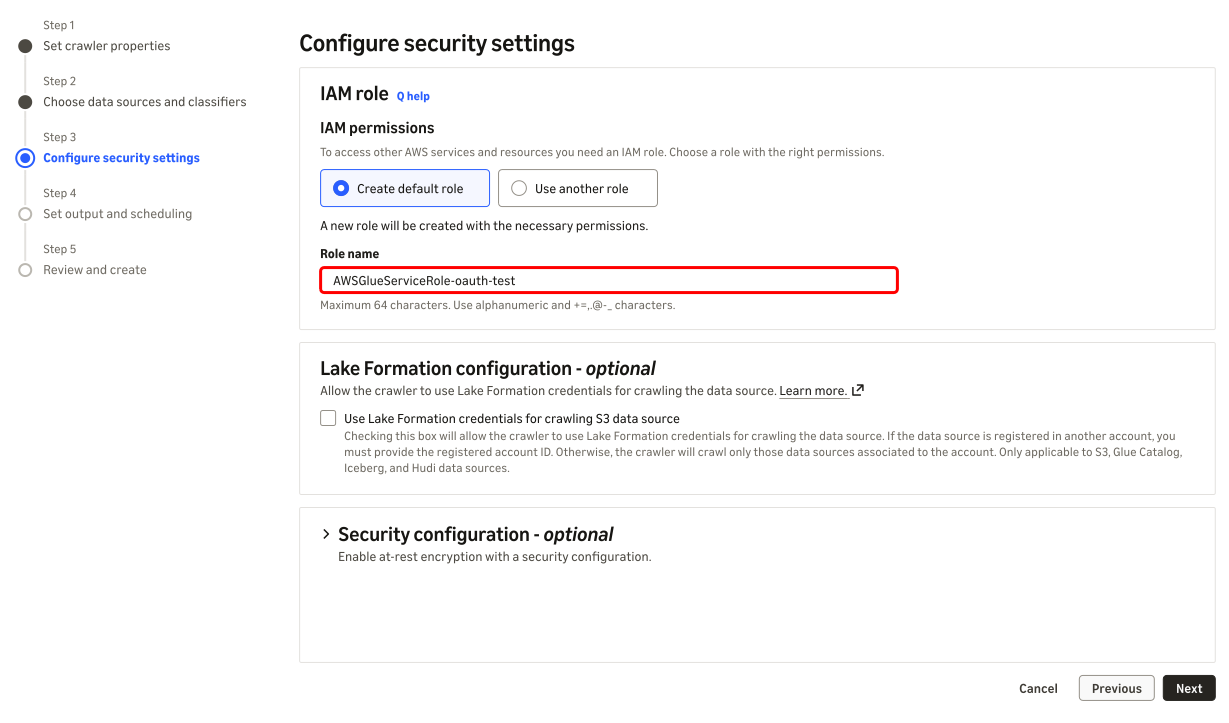
Figure 7 - Using the default role
Point the crawler at the Glue database we created in Figure 2 above, assign a table name prefix of raw_, leave the frequency as On demand, then click Next:
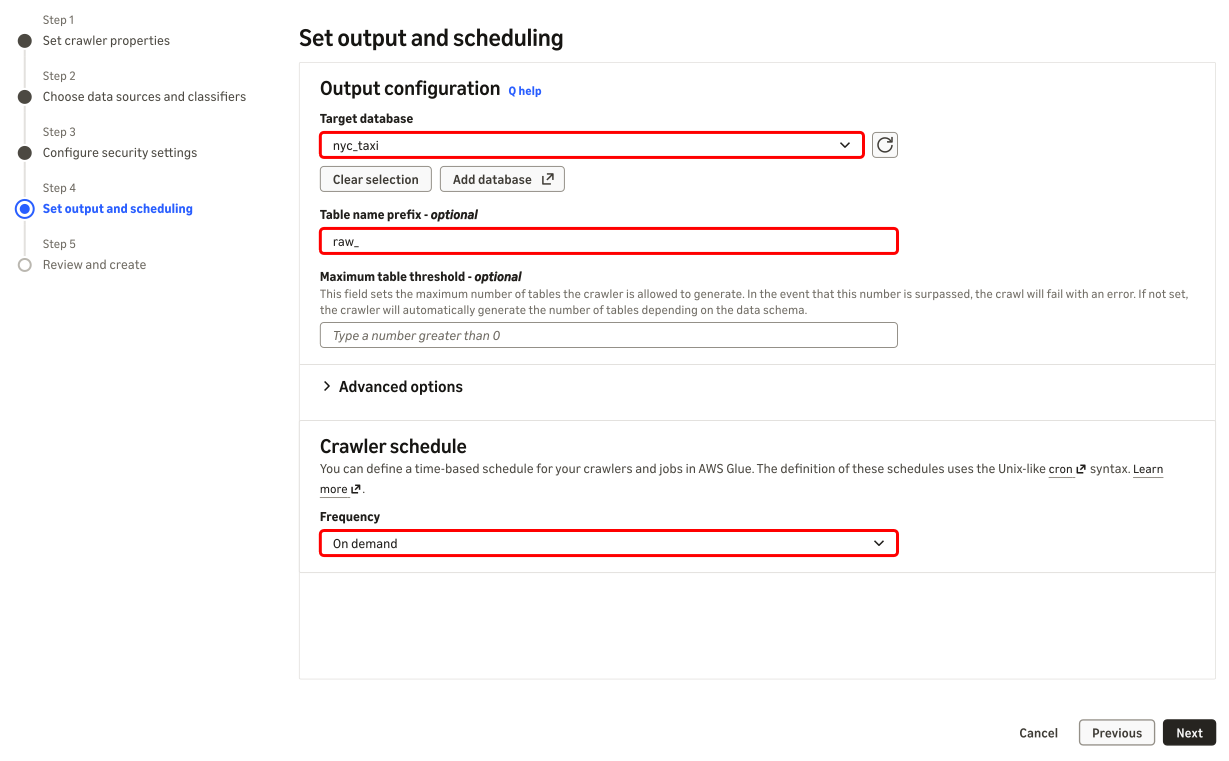
Figure 8 - Setting the crawler’s output and scheduling actions
The options should look like this:
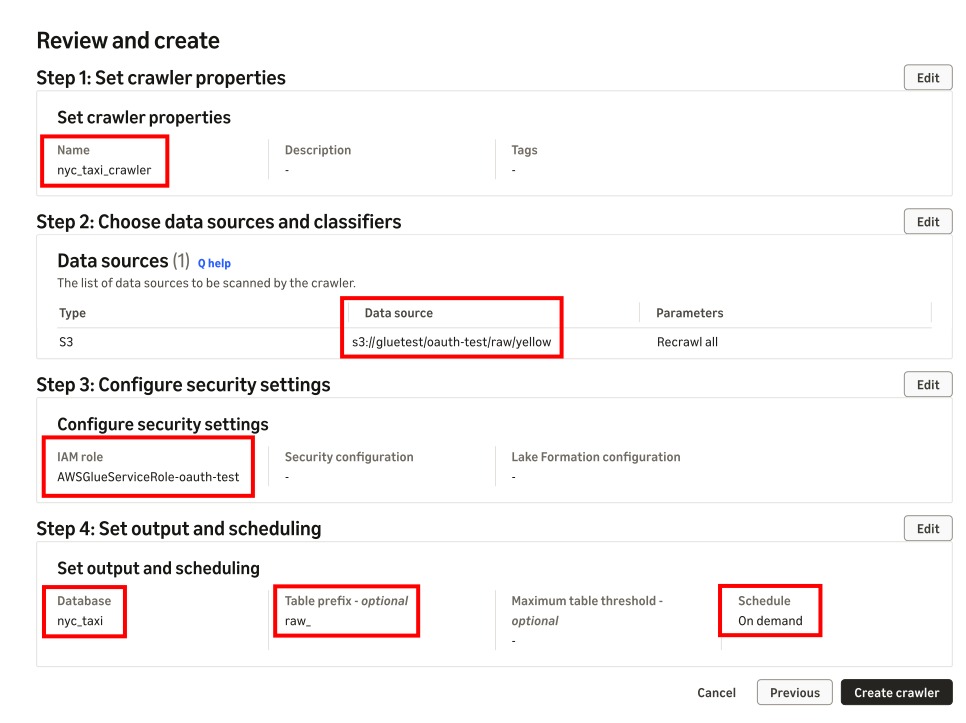
Figure 9 - Complete settings for the crawler
Click the button to create the crawler. When the crawler is ready, click the  button to run it. The Parquet files are in the
raw/yellow/ folder, so the crawler will create a table named raw_yellow inside the nyc_taxi database.
When the run is finished, you’ll get a summary of the results:
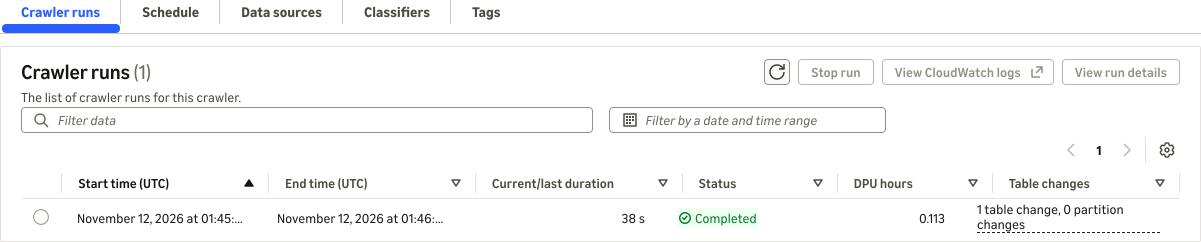
Figure 10 - Results of the crawler run
We’ll run a quick check in the Athena console to make sure the data was processed correctly:
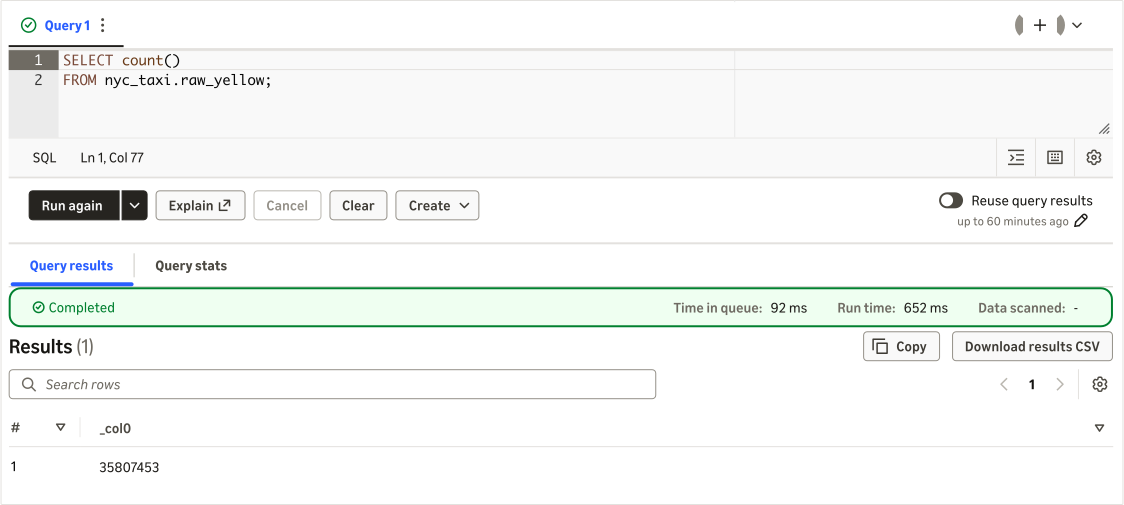
Figure 11 - The raw_yellow table has our data
We’ve got 35.8 million records. Now it’s time to create an Iceberg table from our data.
Creating the Iceberg table
Now we can create the Iceberg table ClickHouse can talk to. Run this command in the Athena console:
CREATE TABLE nyc_taxi.yellow_trips
WITH (
    table_type='ICEBERG',
    location='s3://gluetest/oauth-test/warehouse/yellow_trips',
    is_external = false,
    partitioning = ARRAY['month(tpep_pickup_datetime)']
)
AS
SELECT * FROM nyc_taxi.raw_yellow;
Our Iceberg table (nyc_taxi.yellow_trips) is created by selecting everything from the nyc_taxi.raw_yellow table, generating Parquet files and metadata (notice the data is partitioned by month), and storing everything in the warehouse/yellow_trips/ folder.
For our first step, we used the crawler to interpret the Parquet files and create the schema of our tables. That’s the easiest way to create a schema that matches the data. For this step, we used an SQL statement to create the Iceberg table based on the schema we previously generated. That’s the best way to avoid mismatches between our schema and our data.
When this command is done, we can look in the warehouse/yellow_trips/data/ folder to see where our partitioned data lives:
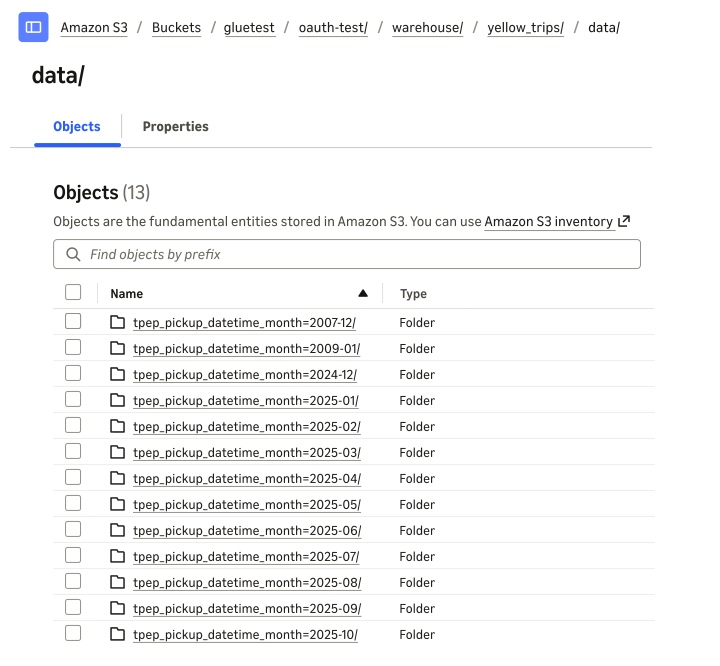
Figure 12 - Partitioned data in our Iceberg catalog
(The NYC Taxi data files always have a few stray records; that’s why we have 13 folders for nine months of data.)
Finally, going back to the Athena console, nyc_taxi.yellow_trips has the same number of records as nyc_taxi.raw_yellow:
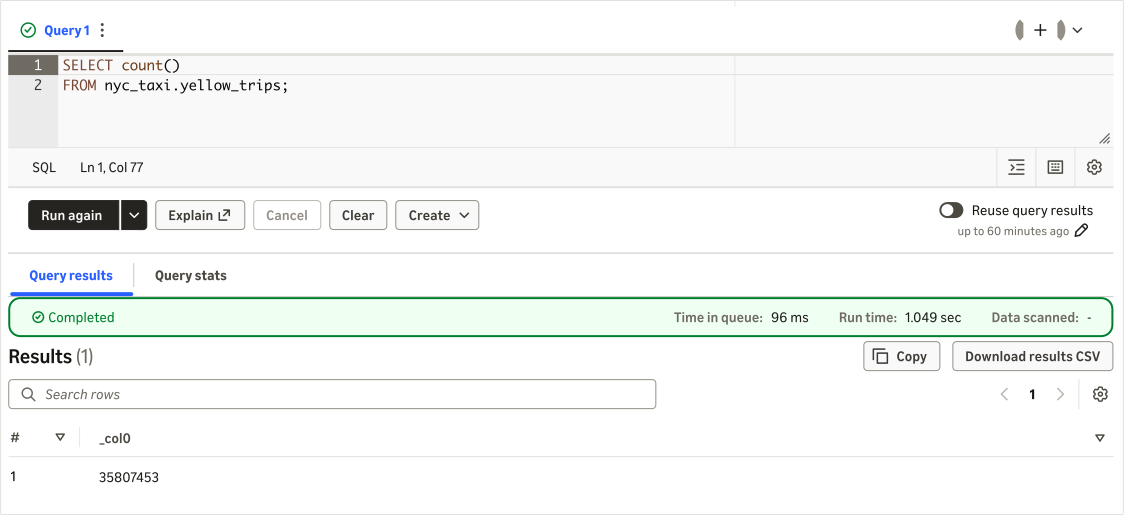
Figure 13 - The new table has the same number of records
At this point, our data lake catalog is done! The next step is to set up the token authentication infrastructure.
Creating the AWS IAM infrastructure
Now that our Iceberg table is in place, we need to set up the infrastructure to manage our tokens. First, we’ll create an identity provider in AWS. We’ll point it to our existing IdP, integrating it with the token infrastructure we’ve already built.
Create a new OIDC provider and give it the URL of your existing IdP and the value of the Audience claim it should look for in a given token:
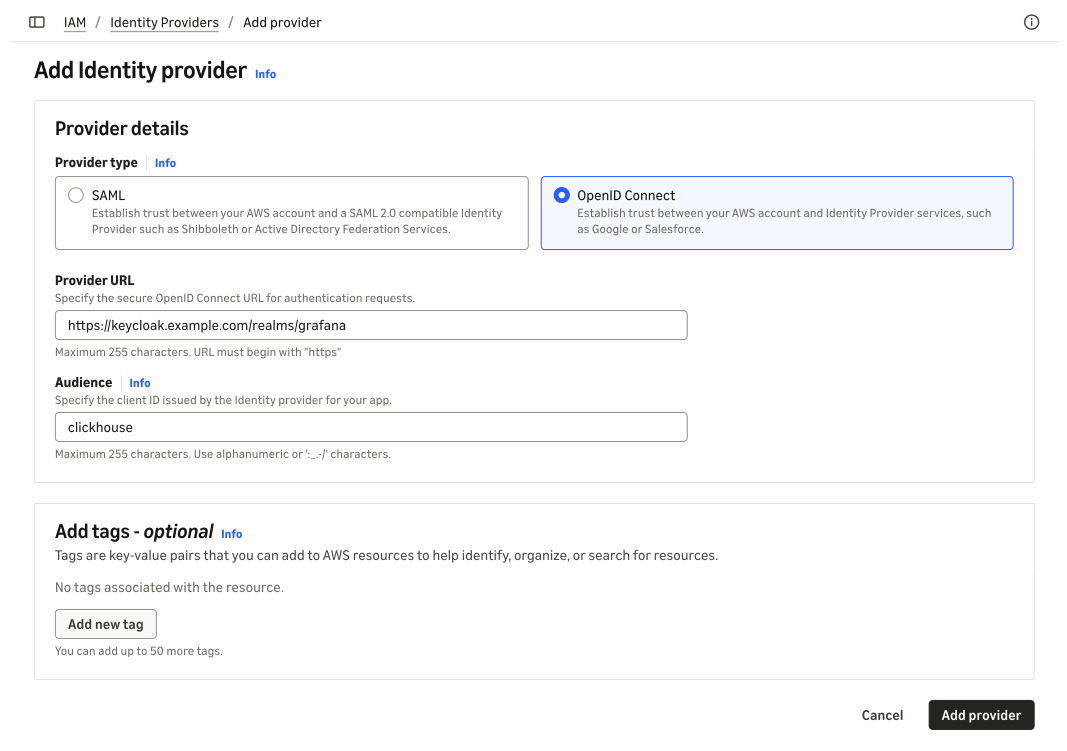
Figure 14 - Creating a new AWS identity provider
We’ve given our new provider the URL of our existing OIDC provider and the value clickhouse as the audience it should look for. We can define multiple audiences if necessary, and we can assign different roles to each. For our example here, we’ll keep it simple with a single audience value.
The Audience value defined in Figure 14 is the value of the aud claim in the authentication token. There are two claims we care about here:
  "iss": "https://keycloak.example.com/realms/grafana",
  "aud": "clickhouse"
The issuer (iss) is the URL of our existing IdP. The Provider URL value in Figure 14 must match that claim exactly. The audience (aud) claim defines the audience for this token.
NOTE
Depending on the IdP that generates your tokens, your JWTs may contain an azp (authorized party) claim. If it exists, the AWS identity provider will ignore the aud claim and look at the value of azp instead.
Check the documentation for the IdP that generates your tokens and the IdP that consumes them inside your cloud provider’s environment to determine how aud and azp claims are generated and handled. (Figuring this out beforehand can save you hours of debugging. Trust us on that.)
With the new identity provider created, you’ll need to assign it a role:
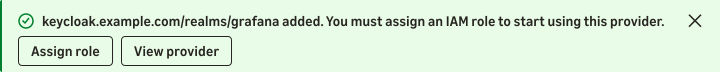
Figure 15 - The new IdP must have a role
Click the Assign role button, then select Create a new rule:
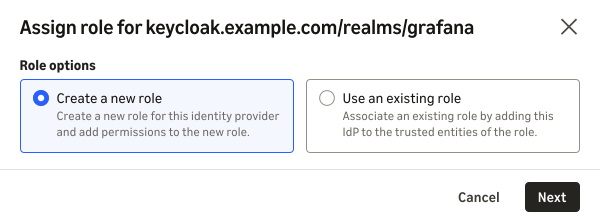
Figure 16 - Assign a new role to the IdP
Next we’ll create a Web identity to define what someone authenticated by the IdP can do. We’ll select Web identity, select the IdP we just created, and the audience we want:
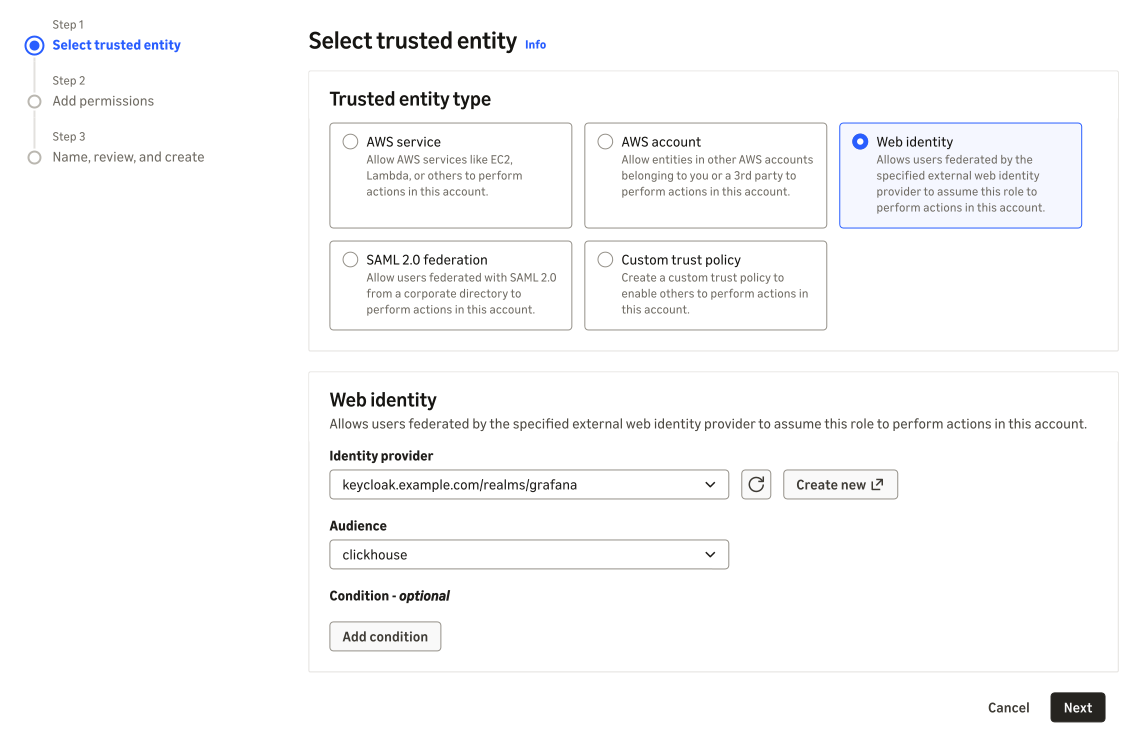
Figure 17 - Creating a Web identity for an IdP / Audience
Click Next. Now we need to add the permissions an authenticated user will have. They’ll need to have permissions from AWS Glue as well as S3. In step 2, choose Create inline policy at the top of the dialog, then paste this into the policy editor:
{
	"Version": "2012-10-17",
	"Statement": [
		{
			"Sid": "GlueRead",
			"Effect": "Allow",
			"Action": [
				"glue:GetDatabase",
				"glue:GetDatabases",
				"glue:GetTable",
				"glue:GetTables"
			],
			"Resource": [
				"arn:aws:glue:us-east-1:123456789012:catalog",
				"arn:aws:glue:us-east-1:123456789012:database/nyc_taxi",
				"arn:aws:glue:us-east-1:123456789012:table/nyc_taxi/*"
			]
		},
		{
			"Sid": "ListWarehouse",
			"Effect": "Allow",
			"Action": "s3:ListBucket",
			"Resource": "arn:aws:s3:::gluetest",
			"Condition": {
				"StringLike": {
					"s3:prefix": "oauth-test/warehouse/*"
				}
			}
		},
		{
			"Sid": "ReadWarehouse",
			"Effect": "Allow",
			"Action": "s3:GetObject",
			"Resource": "arn:aws:s3:::gluetest/oauth-test/warehouse/*"
		}
	]
}
Replace us-east-1 with the AWS region you’re using, replace gluetest with the name of your bucket (it appears twice), and replace 123456789012 with your AWS account number. You’ll see something like this:
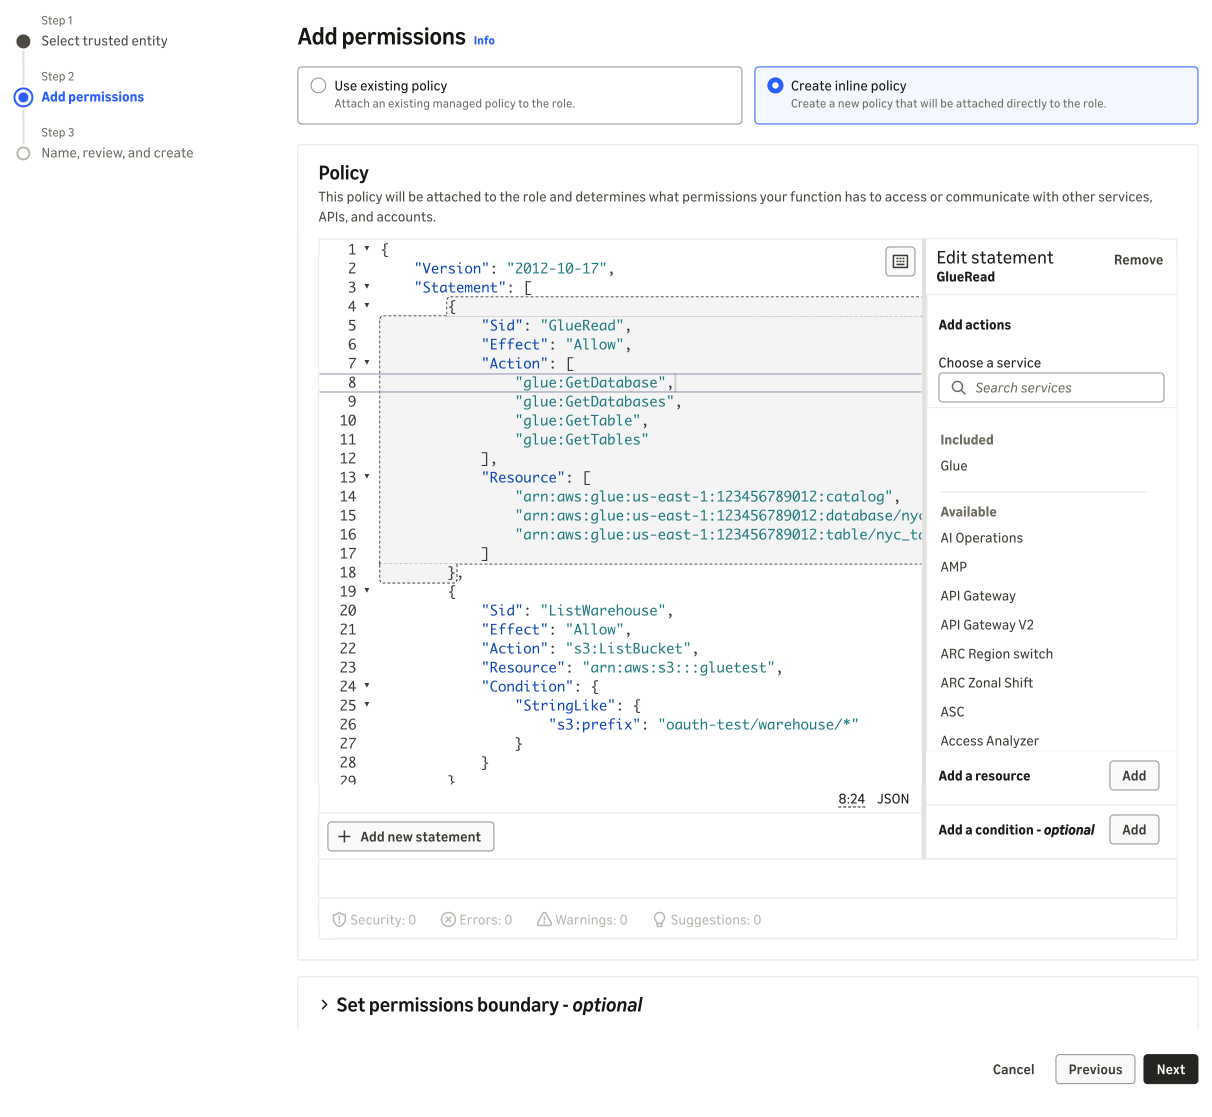
Figure 18 - The inline policy for the new role
Finally, in step 3 we’ll give the policy a name (glue_oauth_reader) and create it. Here’s the complete definition of the role:
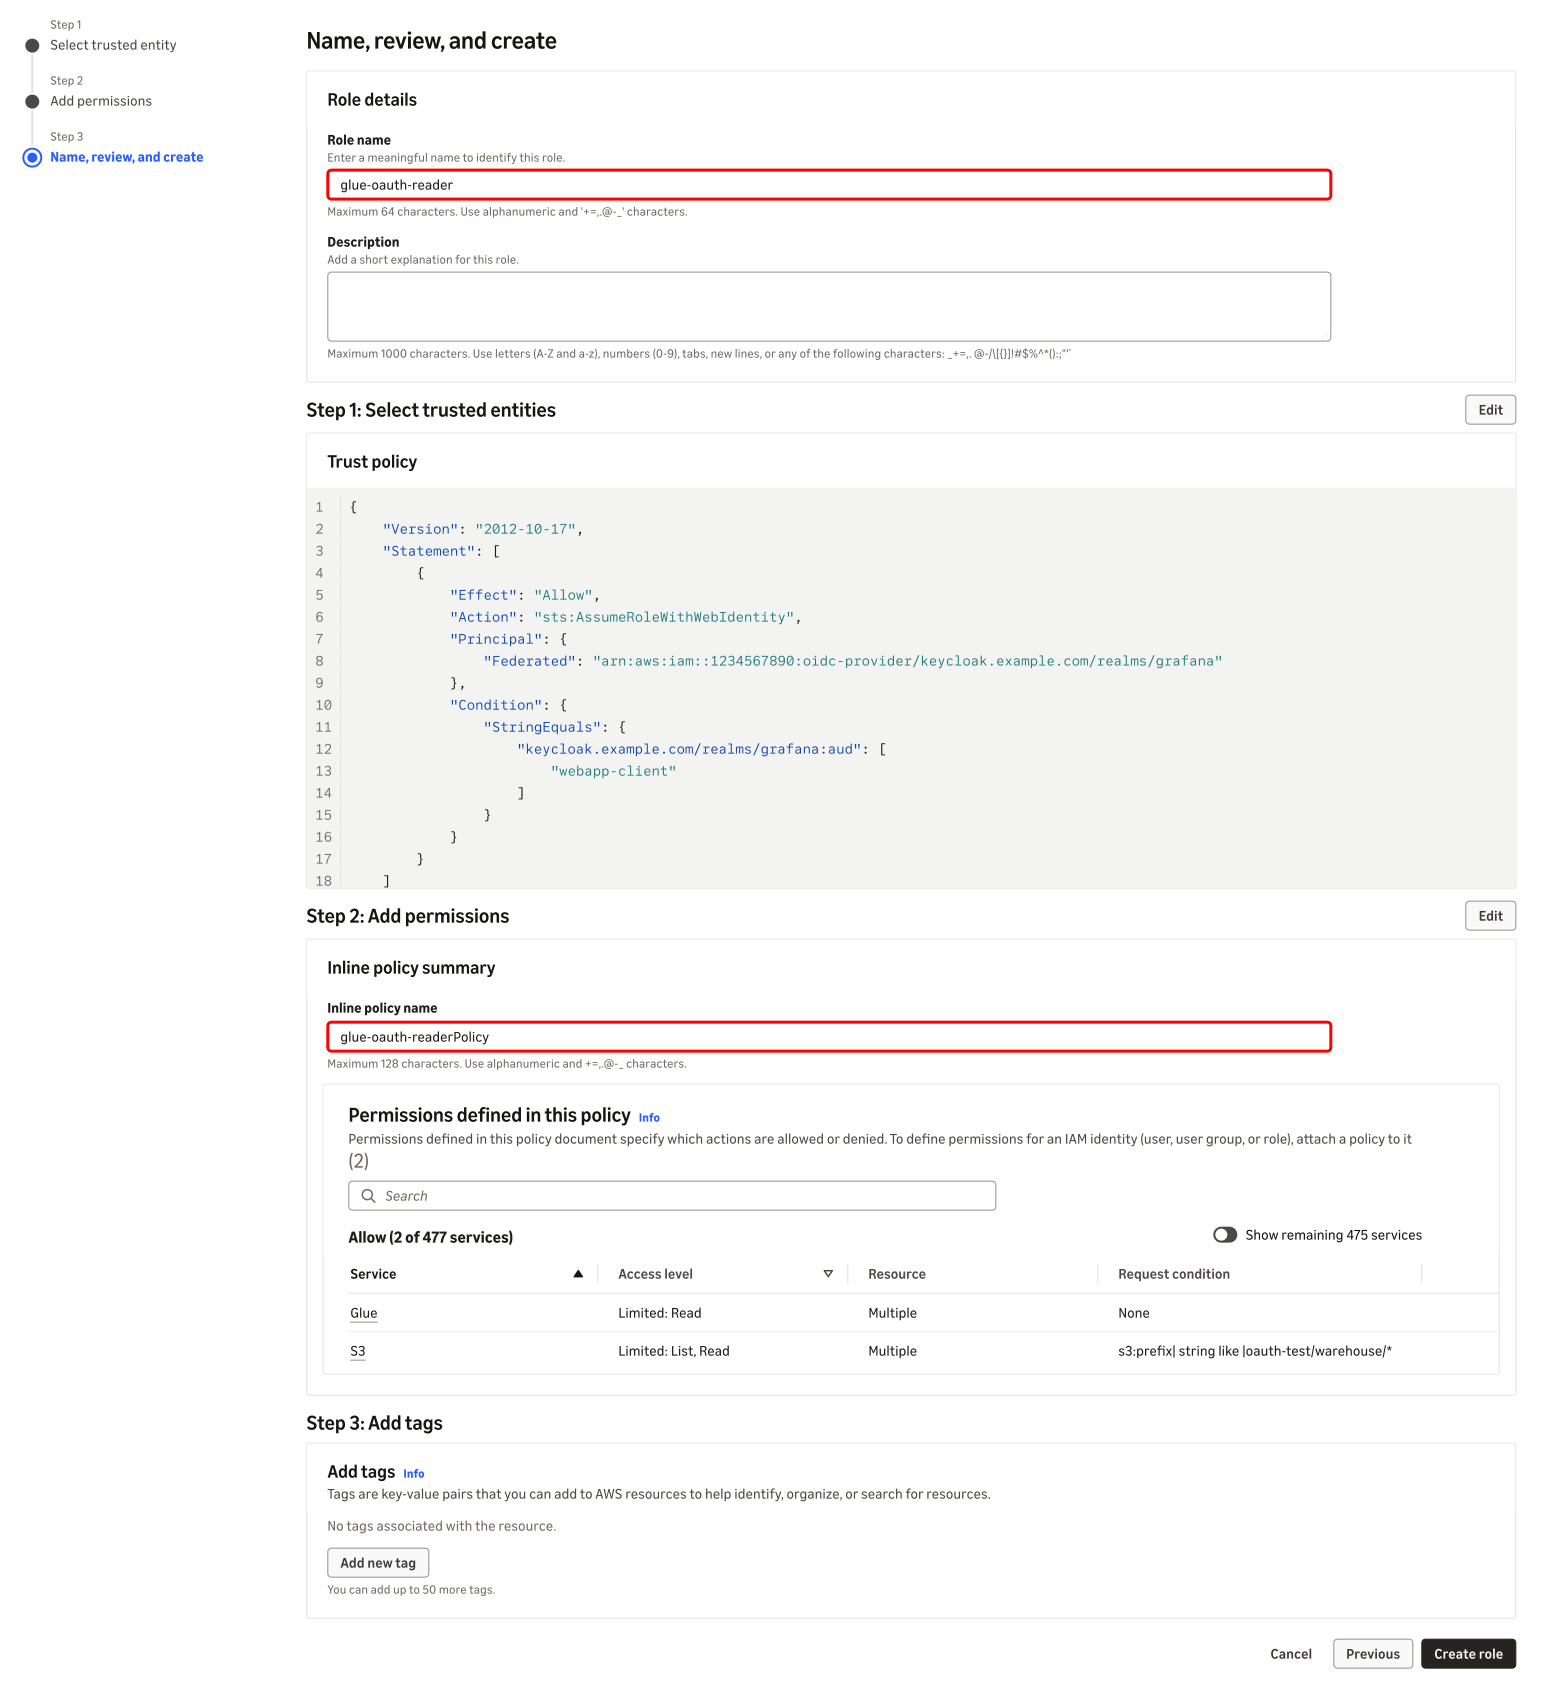
Figure 19 - The complete definition of the new role
The trust policy here identifies our IdP and the audience. AWS generated the name glue-oauth-readerPolicy for our inline policy, and there’s a summary of the permissions in that policy.
Click the  button, and our infrastructure should be all set!
If you’d like to test things out, store a token from your original IdP as $TOKEN, then try this at the command line:
aws sts assume-role-with-web-identity \
  --role-arn arn:aws:iam::123456789012:role/glue-oauth-reader \
  --role-session-name amara \
  --web-identity-token "$TOKEN"
This should return the AWS credentials generated from your token, the audience, the provider, and other information. (This assumes your existing IdP infrastructure defines a user named amara.) If anything is wrong, you’ll get an error message instead.
Creating a DataLakeCatalog database with token forwarding
Now to create our database. Here’s the ClickHouse syntax:
SET allow_experimental_database_glue_catalog = 1;

CREATE DATABASE glue_db
ENGINE = DataLakeCatalog
SETTINGS
    catalog_type = 'glue',
    region = 'us-east-1',
    aws_role_arn = 'arn:aws:iam::123456789012:role/glue-oauth-reader',
    namespaces = 'nyc_taxi',
    oauth_forward_user_token = 1;
We have to turn on the allow_experimental_database_glue_catalog setting for this to work at all. The settings on the CREATE DATABASE command are pretty straightforward. This is an AWS Glue catalog, it’s in the us-east-1 region, we reference the role and database we created, and we turn on token forwarding.
We’ll use the version of clickhouse-client that ships with the version of clickhouse-server that we’re using. Here’s what happens when the default user queries the catalog:
> clickhouse-client
ClickHouse client version 26.6.8.20004.altinityantalya (altinity build).
Connecting to localhost:9000 as user default.
Connected to ClickHouse (antalya:2) server version 26.6.8.

SELECT count()
FROM glue_db.`nyc_taxi.yellow_trips`

Received exception from server (version 26.6.8):
Code: 780. DB::Exception: Received from localhost:9000. DB::Exception: Cannot authenticate to catalog
`Glue(us-east-1)`: this session carries no bearer token. Authenticate with an `Authorization: Bearer`
HTTP header or `--jwt` for the native protocol.. (CATALOG_USER_TOKEN_NOT_AVAILABLE)
However, if the user authenticates with a valid token, everything works:
> clickhouse-client --jwt="eyJrqvAoqP...ujkXbz5Mo2"
ClickHouse client version 26.6.8.20004.altinityantalya (altinity build).
Connecting to localhost:9000.
Connected to ClickHouse (antalya:2) server version 26.6.8.

SELECT count()
FROM glue_db.`nyc_taxi.yellow_trips`

   ┌──count()─┐
1. │ 35807453 │ -- 35.81 million
   └──────────┘
Antalya forwarded the authentication token to AWS Glue, which validated the token, checked the role grated to the token, and returned the data we’re looking for.